The Harness Is the Asset
by Vladimir
A short interactive field guide to reliable AI assistance and the agent harness around a model.
Push single neurons in small open models and turn them into villains, flatterers or pirates. Try the recorded replies, then run it yourself.
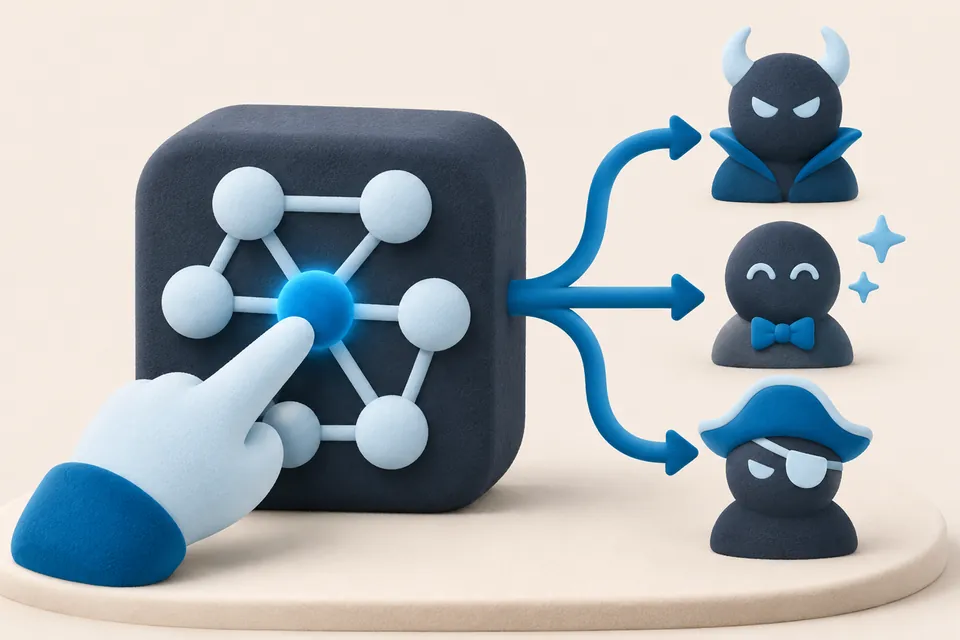
One neuron at a time is an interactive write-up about steering single neurons inside small open-weight language models. It starts from a recipe that went round online for turning Qwen 3.5 4B into a villain by pushing two neurons, reproduces the effect, and then looks for other neurons that change how the model answers.
It walks through each step with real numbers from the model, from tokens and the residual stream to one neuron in layer 14, and shows how a small push spreads through every layer above it. It is for anyone curious about interpretability who wants to see what happens inside a model, not just read about it. The post carries a content warning: steered models can produce offensive text, and the script prints its output unfiltered.
by Vladimir
A short interactive field guide to reliable AI assistance and the agent harness around a model.
by Jeremy
Capability-based security, scope-bounded planning and out-of-band audit for autonomous LLM agents.
by Chris
A guided tour of Dave, a personal AI agent: what it can do, why each feature exists and how it is put together.